mirror of
https://github.com/qdrant/landing_page.git
synced 2026-09-26 14:38:30 +02:00
Merge pull request #193 from qdrant/multitenancy
improve index navigation and info
This commit is contained in:
 David Sertic
@@ -2,40 +2,42 @@
|
||||
title: Qdrant Documentation
|
||||
weight: 10
|
||||
---
|
||||
# Documentation
|
||||
|
||||
# Overview
|
||||
**Qdrant (read: quadrant )** is a vector similarity search engine. Use our documentation to develop a production-ready service with a convenient API to store, search, and manage vectors with an additional payload. Qdrant's expanding features allow for all sorts of neural network or semantic-based matching, faceted search, and other applications.
|
||||
|
||||
Qdrant (read: quadrant ) is a vector similarity search engine. It provides a production-ready service with a convenient API to store, search, and manage points - vectors with an additional payload. Qdrant is tailored to extended filtering support. It makes it useful for all sorts of neural network or semantic-based matching, faceted search, and other applications.
|
||||
## First-Time Users:
|
||||
|
||||
Qdrant is released under the open-source Apache License 2.0. Its source code is available on [GitHub](https://github.com/qdrant/qdrant).
|
||||
There are three ways to use Qdrant:
|
||||
|
||||
## User Manual
|
||||
1. [**Run a Docker image**](quick-start/) if you don't have a Python development environment. Setup a local Qdrant server and storage in a few moments.
|
||||
2. [**Get the Python client**](https://github.com/qdrant/qdrant-client) if you're familiar with Python. Just `pip install qdrant-client`. The client uses an in-memory database.
|
||||
3. [**Spin up a Qdrant Cloud cluster:**](cloud/) the recommended method to run Qdrant in production. Read [Quickstart](cloud/cloud-quick-start/) to setup your first instance.
|
||||
|
||||
Read more about our [key concepts](../documentation/concepts/points/) and visit our [guides](../documentation/guides/installation/) to set up and further configure Qdrant for your own use.
|
||||
### Recommended Workflow:
|
||||
|
||||
## Tutorials
|
||||
|
||||
|
||||
Check out the Tutorials section to learn more about common use cases. Qdrant is ideal for deploying applications based on the matching of embeddings produced by neural network encoders.
|
||||
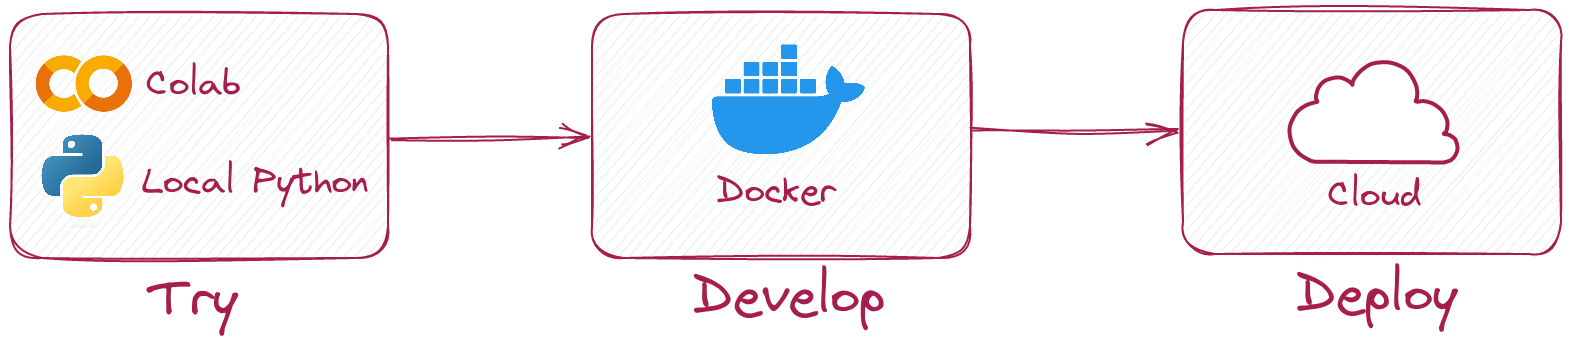
First, try Qdrant locally using the [Qdrant Client](https://github.com/qdrant/qdrant-client) and with the help of our [Tutorials](tutorials/) and Guides. Develop a sample app from our [Examples](examples/) list and try it using a [Qdrant Docker](guides/installation/) container. Then, when you are ready for production, deploy to a Free Tier [Qdrant Cloud](cloud/) cluster.
|
||||
|
||||
These can be:
|
||||
## Popular Topics:
|
||||
|
||||
- Semantic search
|
||||
- Similar Image \ Audio \ Video search
|
||||
- Recommendation systems
|
||||
| Tutorial | Description | Tutorial| Description |
|
||||
|----------------------------------------------------|----------------------------------------------|---------|------------------|
|
||||
| [Installation](guides/installation/) | Different ways to install Qdrant. | [Collections](concepts/collections/) | Learn about the central concept behind Qdrant. |
|
||||
| [Configuration](guides/configuration/) | Update the default configuration. | [Bulk Upload](tutorials/bulk-upload/) | Efficiently upload a large number of vectors. |
|
||||
| [Optimization](tutorials/optimize/) | Optimize Qdrant's resource usage. | [Multitenancy](tutorials/multiple-partitions/) | Setup Qdrant for multiple independent users. |
|
||||
|
||||
In addition to this documentation, you may be interested in looking at examples of projects made with Qdrant:
|
||||
## Common Use Cases:
|
||||
|
||||
- [Semantic Search for startups](https://demo.qdrant.tech/) + [Source Code](https://github.com/qdrant/qdrant_demo)
|
||||
- [Visual Food Discovery](https://food-discovery.qdrant.tech/)
|
||||
- [Step-by-Step tutorial on building neural search](/articles/neural-search-tutorial/)
|
||||
Qdrant is ideal for deploying applications based on the matching of embeddings produced by neural network encoders. Check out the [Examples](examples/) section to learn more about common use cases. Also, you can visit the [Tutorials](tutorials/) page to learn how to work with Qdrant in different ways.
|
||||
|
||||
|
||||
## Integrations
|
||||
|
||||
Qdrant is a vector database performing an approximate nearest neighbours search on neural embeddings. It can work perfectly fine
|
||||
as a standalone system, yet, in some cases, you may find it easier to implement your semantic search application using some
|
||||
higher-level libraries. Visit our Integrations section to learn more.
|
||||
|
||||
## Get started
|
||||
|
||||
Go to the [Quickstart](../documentation/quick-start/) guide to get a production-ready vector search service up and running in minutes.
|
||||
| Use Case | Description | Stack |
|
||||
|-----------------------|----------------------------------------------|--------|
|
||||
| [Intro to Semantic Search and Recommendations Systems](https://githubtocolab.com/qdrant/examples/blob/master/qdrant_101_getting_started/getting_started.ipynb) | Learn how to get started building semantic search and recommendation systems. | Qdrant |
|
||||
| [Build a Simple Neural Search](tutorials/neural-search/) | Build and deploy a neural search. [Check out the live demo app.](https://demo.qdrant.tech/#/) | Qdrant, BERT, FastAPI |
|
||||
| [Build a Search with Aleph Alpha](tutorials/aleph-alpha-search/) | Build a simple semantic search that combines text and image data. | Qdrant, Aleph Alpha |
|
||||
| [Search and Recommend Newspaper Articles](https://githubtocolab.com/qdrant/examples/blob/master/qdrant_101_text_data/qdrant_and_text_data.ipynb) | Work with text data to develop a semantic search and a recommendation engine for news articles. | Qdrant |
|
||||
| [Recommendation System for Songs](https://githubtocolab.com/qdrant/examples/blob/master/qdrant_101_audio_data/03_qdrant_101_audio.ipynb) | Use Qdrant to develop a music recommendation engine based on audio embeddings. | Qdrant |
|
||||
| [Image Comparison System for Skin Conditions](https://colab.research.google.com/github/qdrant/examples/blob/master/qdrant_101_image_data/04_qdrant_101_cv.ipynb) | Use Qdrant to compare challenging images with labels representing different skin diseases. | Qdrant |
|
||||
| [Question and Answer System with LlamaIndex](https://githubtocolab.com/qdrant/examples/blob/master/llama_index_recency/Qdrant%20and%20LlamaIndex%20%E2%80%94%20A%20new%20way%20to%20keep%20your%20Q%26A%20systems%20up-to-date.ipynb) | Combine Qdrant and LlamaIndex to create a self-updating Q&A system. | Qdrant, LlamaIndex, Cohere |
|
||||
@@ -14,4 +14,5 @@ Our Notebooks offer complex instructions that are supported with a throrough exp
|
||||
| [Intro to Semantic Search and Recommendations Systems](https://githubtocolab.com/qdrant/examples/blob/master/qdrant_101_getting_started/getting_started.ipynb) | Learn how to get started building semantic search and recommendation systems. | Qdrant |
|
||||
| [Search and Recommend Newspaper Articles](https://githubtocolab.com/qdrant/examples/blob/master/qdrant_101_text_data/qdrant_and_text_data.ipynb) | Work with text data to develop a semantic search and a recommendation engine for news articles. | Qdrant |
|
||||
| [Recommendation System for Songs](https://githubtocolab.com/qdrant/examples/blob/master/qdrant_101_audio_data/03_qdrant_101_audio.ipynb) | Use Qdrant to develop a music recommendation engine based on audio embeddings. | Qdrant |
|
||||
| [Question and Answer System with LlamaIndex](https://githubtocolab.com/qdrant/examples/blob/master/llama_index_recency/Qdrant%20and%20LlamaIndex%20%E2%80%94%20A%20new%20way%20to%20keep%20your%20Q%26A%20systems%20up-to-date.ipynb) | Combine Qdrant and LlamaIndex to create a self-updating Q&A system. | Qdrant, LlamaIndex, Cohere |
|
||||
| [Image Comparison System for Skin Conditions](https://colab.research.google.com/github/qdrant/examples/blob/master/qdrant_101_image_data/04_qdrant_101_cv.ipynb) | Use Qdrant to compare challenging images with labels representing different skin diseases. | Qdrant |
|
||||
| [Question and Answer System with LlamaIndex](https://githubtocolab.com/qdrant/examples/tree/master/llama_index_recency/Qdrant%20and%20LlamaIndex%20%E2%80%94%20A%20new%20way%20to%20keep%20your%20Q%26A%20systems%20up-to-date.ipynb) | Combine Qdrant and LlamaIndex to create a self-updating Q&A system. | Qdrant, LlamaIndex, Cohere |
|
||||
|
||||
@@ -1,23 +1,32 @@
|
||||
---
|
||||
title: Separate partitions
|
||||
title: Configure Multitenancy
|
||||
weight: 12
|
||||
---
|
||||
# Configure Multitenancy
|
||||
|
||||
# Serve vectors for many independent users
|
||||
When an instance is shared between multiple users, you may need to partition vectors by user.
|
||||
This is done so that each user can only access their own vectors and can't see the vectors of other users.
|
||||
|
||||
This is a common use case when you want to provide vector search for multiple independent partitions.
|
||||
These partitions may be divided by users, organizations, or other criteria.
|
||||
However, for simplicity, we will refer to them as users.
|
||||
Before you configure multitenancy in Qdrant, you must consider the following:
|
||||
- The number of users in your tenancy structure;
|
||||
- Individual user performance needs;
|
||||
- Resource overhead and budget allowance.
|
||||
|
||||
Each user should have only access to their own vectors and should not be able to view the vectors of other users.
|
||||
Qdrant supports multitenancy in two ways:
|
||||
|
||||
There are several ways to achieve this in Qdrant:
|
||||
## Multiple collections per user
|
||||
|
||||
- Use multiple collections, one for each user. This approach is the most flexible, but creating numerous collections may result in resource overhead. It is only recommended to separate users into multiple collections if you have a limited number of users and need to ensure that they do not affect each other in any way, including performance-wise.
|
||||
You may always create a collection for each user. This approach is flexible, but it may be more costly, since creating numerous collections may result in resource overhead. We recommend you do this only if you have a limited number of users, and you need to ensure that they do not affect each other in any way, including performance-wise.
|
||||
|
||||
- Use a single collection with payload-based partitioning. This approach is more efficient for a large number of users but requires some additional preparations.
|
||||
>**Tutorial:** Learn how to [create a collection](../../concepts/collections/).
|
||||
|
||||
In a simple case, it is sufficient to add a `group_id` field to each vector in the collection and use a filter along with `group_id` to filter vectors for each user.
|
||||
## Partition collection by payload
|
||||
|
||||
In most cases, you should use a single collection with payload-based partitioning.
|
||||
This approach is more efficient for a large number of users, but it requires additional configuration.
|
||||
|
||||
1. First, add a `group_id` field to each vector in the collection.
|
||||
2. Then, use a filter along with `group_id` to filter vectors for each user.
|
||||
|
||||
```http
|
||||
PUT /collections/{collection_name}/points
|
||||
@@ -66,7 +75,7 @@ client.upsert(
|
||||
)
|
||||
```
|
||||
|
||||
And search with `group_id` filter:
|
||||
3. You can search with the `group_id` filter:
|
||||
|
||||
```http
|
||||
POST /collections/{collection_name}/points/search
|
||||
@@ -108,18 +117,17 @@ client.search(
|
||||
limit=10,
|
||||
)
|
||||
```
|
||||
## Calibrate performance
|
||||
|
||||
However, the speed of indexation may become a bottleneck in this case, as each user's vector will be indexed into the same collection. To avoid this bottleneck, consider _bypassing the construction of a global vector index_ for the entire collection and building it only for individual groups instead.
|
||||
The speed of indexation may become a bottleneck in this case, as each user's vector will be indexed into the same collection. To avoid this bottleneck, consider _bypassing the construction of a global vector index_ for the entire collection and building it only for individual groups instead.
|
||||
|
||||
By adopting this strategy, Qdrant will index vectors for each user independently, significantly accelerating the process.
|
||||
|
||||
One downside to this approach is that global requests (without the `group_id` filter) will be slower since they will necessitate scanning all groups to identify the nearest neighbors.
|
||||
|
||||
To implement this approach, you should:
|
||||
|
||||
- Set `payload_m` in the HNSW configuration to a non-zero value, such as 16.
|
||||
- set `m` in hnsw config to 0. This will disable building global index for the whole collection
|
||||
- Create keyword payload index for `group_id` field.
|
||||
1. Set `payload_m` in the HNSW configuration to a non-zero value, such as 16.
|
||||
2. Set `m` in hnsw config to 0. This will disable building global index for the whole collection.
|
||||
3. Create keyword payload index for `group_id` field.
|
||||
|
||||
```http
|
||||
PUT /collections/{collection_name}
|
||||
@@ -169,3 +177,7 @@ client.create_payload_index(
|
||||
field_schema=models.PayloadSchemaType.KEYWORD
|
||||
)
|
||||
```
|
||||
|
||||
## Limitations
|
||||
|
||||
One downside to this approach is that global requests (without the `group_id` filter) will be slower since they will necessitate scanning all groups to identify the nearest neighbors.
|
||||
|
||||
Reference in New Issue
Block a user