mirror of
https://github.com/qdrant/landing_page.git
synced 2026-09-28 23:48:31 +02:00
Merge branch 'master' into gui-quickstart
This commit is contained in:
 davidmyriel
@@ -70,7 +70,7 @@ For 100K OpenAI Embedding (`ada-002`) vectors we would need 900 Megabytes of RAM
|
||||
|
||||
**With binary quantization, those same 100K OpenAI vectors only require 128 MB of RAM.** We benchmarked this result using methods similar to those covered in our [Scalar Quantization memory estimation](/articles/scalar-quantization/#benchmarks).
|
||||
|
||||
This reduction in RAM needed is achieved through the compression that happens in the binary conversion. Instead of putting the HNSW index for the full vectors into RAM, we just put the binary vectors into RAM, use them for the initial oversampled search, and then use the HNSW full index of the oversampled results for the final precise search. All of this happens under the hoods without any intervention needed on your part.
|
||||
This reduction in RAM usage is achieved through the compression that happens in the binary conversion. HNSW and quantized vectors will live in RAM for quick access, while original vectors can be offloaded to disk only. For searching, quantized HNSW will provide oversampled candidates, then they will be re-evaluated using their disk-stored original vectors to refine the final results. All of this happens under the hood without any additional intervention on your part.
|
||||
|
||||
### When should you not use BQ?
|
||||
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
---
|
||||
title: "Discovery Search: A New Approach to Vector Space"
|
||||
short_description: Discovery Search, an innovative API for precise, tailored search results.
|
||||
description: Explore the next frontier in search technology with Discovery Search. Learn how this innovative API provides precise and tailored results.
|
||||
title: "Discovery needs context"
|
||||
short_description: Discover points by constraining the vector space.
|
||||
description: Discovery Search, an innovative way to constrain the vector space in which a search is performed, relying only on vectors.
|
||||
social_preview_image: /articles_data/discovery-search/social_preview.jpg
|
||||
small_preview_image: /articles_data/discovery-search/icon.svg
|
||||
preview_dir: /articles_data/discovery-search/preview
|
||||
@@ -14,28 +14,24 @@ keywords:
|
||||
- why use a vector database
|
||||
- specialty
|
||||
- search
|
||||
- discovery
|
||||
- multimodal
|
||||
- state-of-the-art
|
||||
- vector-search
|
||||
---
|
||||
|
||||
# How to Master Vector Space Exploration with Discovery Search
|
||||
# Discovery needs context
|
||||
|
||||
When Christopher Columbus and his crew sailed to cross the Atlantic Ocean, they were not looking for America. They were looking for a new route to India, and they were convinced that the Earth was round. They didn't know anything about America, but since they were going west, they stumbled upon it.
|
||||
When Christopher Columbus and his crew sailed to cross the Atlantic Ocean, they were not looking for the Americas. They were looking for a new route to India because they were convinced that the Earth was round. They didn't know anything about a new continent, but since they were going west, they stumbled upon it.
|
||||
|
||||
They couldn't reach their _target_, because the geography didn't let them, but once they realized it wasn't India, they claimed it a new "discovery" for their crown. If we consider that sailors need water to sail, then we can establish a _context_ which is positive in the water, and negative on land. Once the sailor's search was stopped by the land, they could not go any further, and a new route was found. Let's keep these concepts of _target_ and _context_ in mind as we explore the new functionality of Qdrant: __Discovery search__.
|
||||
|
||||
## What is discovery search?
|
||||
|
||||
Discovery search is a powerful tool that lets you explore the vector space in a more controlled way. It can be used to find points that are not necessarily close to the target but are still relevant to the search. It can also be used to represent complex tastes and break out of the similarity bubble. Check out the documentation to learn more about the math behind it and how to use it.
|
||||
|
||||
## Qdrant's discovery search: version 1.7 release
|
||||
|
||||
In version 1.7, Qdrant [released](/articles/qdrant-1.7.x/) this novel API that lets you constrain the space in which a search is performed, relying only on pure vectors. This is a powerful tool that lets you explore the vector space in a more controlled way. It can be used to find points that are not necessarily closest to the target, but are still relevant to the search.
|
||||
|
||||
You can already select which points are available to the search by using payload filters. This by itself is very versatile because it allows us to craft complex filters that show only the points that satisfy their criteria deterministically. However, the payload associated with each point is arbitrary and cannot tell us anything about their position in the vector space. In other words, filtering out irrelevant points can be seen as creating a _mask_ rather than a hyperplane –cutting in between the positive and negative vectors– in the space.
|
||||
|
||||
## Understanding context in discovery search
|
||||
## Understanding context
|
||||
|
||||
This is where a __vector _context___ can help. We define _context_ as a list of pairs. Each pair is made up of a positive and a negative vector. With a context, we can define hyperplanes within the vector space, which always prefer the positive over the negative vectors. This effectively partitions the space where the search is performed. After the space is partitioned, we then need a _target_ to return the points that are more similar to it.
|
||||
|
||||
@@ -99,8 +95,8 @@ Creating complex tastes in a high-dimensional space becomes easier since you can
|
||||
|
||||
This way you can give refreshing recommendations, while still being in control by providing positive and negative feedback, or even by trying out different permutations of pairs.
|
||||
|
||||
## Key rakeaways:
|
||||
## Key takeaways:
|
||||
- Discovery search is a powerful tool for controlled exploration in vector spaces.
|
||||
Context, positive, and negative vectors guide search parameters and refine results.
|
||||
Context, consisting of positive and negative vectors constrain the search space, while a target guides the search.
|
||||
- Real-world applications include multimodal search, diverse recommendations, and context-driven exploration.
|
||||
- Ready to experience the power of Qdrant's Discovery search for yourself? [Try a free demo](https://qdrant.tech/contact-us/) now and unlock the full potential of controlled exploration in vector spaces!
|
||||
- Ready to learn more about the math behind it and how to use it? Check out the [documentation](/documentation/concepts/explore/#discovery-api)
|
||||
@@ -23,7 +23,8 @@ tags:
|
||||
**Multivector Support:** Native support for late interaction ColBERT is accessible via Query API.
|
||||
|
||||
## One Endpoint for All Queries
|
||||
**Query API** will consolidate all search APIs into a single request. Previously, you had to work outside of the API to combine different search requests. Now these approaches are reduced to parameters of a single request, so you can avoid merging individual results.
|
||||
|
||||
**Query API** will consolidate all search APIs into a single request. Previously, you had to work outside of the API to combine different search requests. Now these approaches are reduced to parameters of a single request, so you can avoid merging individual results.
|
||||
|
||||
You can now configure the Query API request with the following parameters:
|
||||
|
||||
@@ -59,7 +60,8 @@ POST collections/{collection_name}/points/query
|
||||
We will be publishing code samples in [docs](/documentation/concepts/hybrid-queries/) and our new [API specification](http://api.qdrant.tech).</br> *If you need additional support with this new method, our [Discord](https://qdrant.to/discord) on-call engineers can help you.*
|
||||
|
||||
### Native Hybrid Search Support
|
||||
Query API now also natively supports **sparse/dense fusion**. Up to this point, you had to combine the results of sparse and dense searches on your own. This is now sorted on the back-end, and you only have to configure them as basic parameters for Query API.
|
||||
|
||||
Query API now also natively supports **sparse/dense fusion**. Up to this point, you had to combine the results of sparse and dense searches on your own. This is now sorted on the back-end, and you only have to configure them as basic parameters for Query API.
|
||||
|
||||
```http
|
||||
POST /collections/{collection_name}/points/query
|
||||
@@ -84,6 +86,56 @@ POST /collections/{collection_name}/points/query
|
||||
}
|
||||
```
|
||||
|
||||
```python
|
||||
from qdrant_client import QdrantClient, models
|
||||
|
||||
client = QdrantClient(url="http://localhost:6333")
|
||||
|
||||
client.query_points(
|
||||
collection_name="{collection_name}",
|
||||
prefetch=[
|
||||
models.Prefetch(
|
||||
query=models.SparseVector(indices=[1, 42], values=[0.22, 0.8]),
|
||||
using="sparse",
|
||||
limit=20,
|
||||
),
|
||||
models.Prefetch(
|
||||
query=[0.01, 0.45, 0.67],
|
||||
using="dense",
|
||||
limit=20,
|
||||
),
|
||||
],
|
||||
query=models.FusionQuery(fusion=models.Fusion.RRF),
|
||||
)
|
||||
```
|
||||
|
||||
```typescript
|
||||
import { QdrantClient } from "@qdrant/js-client-rest";
|
||||
|
||||
const client = new QdrantClient({ host: "localhost", port: 6333 });
|
||||
|
||||
client.query("{collection_name}", {
|
||||
prefetch: [
|
||||
{
|
||||
query: {
|
||||
values: [0.22, 0.8],
|
||||
indices: [1, 42],
|
||||
},
|
||||
using: 'sparse',
|
||||
limit: 20,
|
||||
},
|
||||
{
|
||||
query: [0.01, 0.45, 0.67],
|
||||
using: 'dense',
|
||||
limit: 20,
|
||||
},
|
||||
],
|
||||
query: {
|
||||
fusion: 'rrf',
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
```rust
|
||||
use qdrant_client::Qdrant;
|
||||
use qdrant_client::qdrant::{Fusion, PrefetchQueryBuilder, Query, QueryPointsBuilder};
|
||||
@@ -167,7 +219,7 @@ await client.QueryAsync(
|
||||
);
|
||||
```
|
||||
|
||||
Query API can now pre-fetch vectors for requests, which means you can run queries sequentially within the same API call. There are a lot of options here, so you will need to define a strategy to merge these requests using new parameters. For example, you can now include **rescoring within Hybrid Search**, which can open the door to strategies like iterative refinement via matryoshka embeddings.
|
||||
|
||||
*To learn more about this, read the [Query API documentation](/documentation/concepts/search/#query-api).*
|
||||
|
||||
@@ -214,6 +266,20 @@ client.create_collection(
|
||||
)
|
||||
```
|
||||
|
||||
```typescript
|
||||
import { QdrantClient } from "@qdrant/js-client-rest";
|
||||
|
||||
const client = new QdrantClient({ host: "localhost", port: 6333 });
|
||||
|
||||
client.createCollection("{collection_name}", {
|
||||
sparse_vectors: {
|
||||
"text": {
|
||||
modifier: "idf"
|
||||
}
|
||||
}
|
||||
});
|
||||
```
|
||||
|
||||
```rust
|
||||
use qdrant_client::Qdrant;
|
||||
use qdrant_client::qdrant::{CreateCollectionBuilder, sparse_vectors_config::SparseVectorsConfigBuilder, Modifier, SparseVectorParamsBuilder};
|
||||
@@ -282,12 +348,13 @@ In practical terms, the BM42 method addresses the tokenization issues and comput
|
||||
|
||||
**You can expect BM42 to excel in scalable RAG-based scenarios where short texts are more common.** Document inference speed is much higher with BM42, which is critical for large-scale applications such as search engines, recommendation systems, and real-time decision-making systems.
|
||||
|
||||
## Multivector Support
|
||||
We are adding native support for multivector search that is compatible, e.g., with the late-interaction [ColBERT](https://github.com/stanford-futuredata/ColBERT) model. If you are working with high-dimensional similarity searches, **ColBERT is highly recommended as a reranking step in the Universal Query search.** You will experience better quality vector retrieval since ColBERT’s approach allows for deeper semantic understanding.
|
||||
## Multivector Support
|
||||
|
||||
This model retains contextual information during query-document interaction, leading to better relevance scoring. In terms of efficiency and scalability benefits, documents and queries will be encoded separately, which gives an opportunity for pre-computation and storage of document embeddings for faster retrieval.
|
||||
We are adding native support for multivector search that is compatible, e.g., with the late-interaction [ColBERT](https://github.com/stanford-futuredata/ColBERT) model. If you are working with high-dimensional similarity searches, **ColBERT is highly recommended as a reranking step in the Universal Query search.** You will experience better quality vector retrieval since ColBERT’s approach allows for deeper semantic understanding.
|
||||
|
||||
**Note:** *This feature supports all the original quantization compression methods, just the same as the regular search method.*
|
||||
This model retains contextual information during query-document interaction, leading to better relevance scoring. In terms of efficiency and scalability benefits, documents and queries will be encoded separately, which gives an opportunity for pre-computation and storage of document embeddings for faster retrieval.
|
||||
|
||||
**Note:** *This feature supports all the original quantization compression methods, just the same as the regular search method.*
|
||||
|
||||
**Run a query with ColBERT vectors:**
|
||||
|
||||
@@ -316,6 +383,55 @@ POST /collections/{collection_name}/points/query
|
||||
}
|
||||
```
|
||||
|
||||
```python
|
||||
from qdrant_client import QdrantClient, models
|
||||
|
||||
client = QdrantClient(url="http://localhost:6333")
|
||||
|
||||
client.query_points(
|
||||
collection_name="{collection_name}",
|
||||
prefetch=models.Prefetch(
|
||||
prefetch=models.Prefetch(query=[1, 23, 45, 67], using="mrl_byte", limit=1000),
|
||||
query=[0.01, 0.45, 0.67],
|
||||
using="full",
|
||||
limit=100,
|
||||
),
|
||||
query=[
|
||||
[0.1, 0.2],
|
||||
[0.2, 0.1],
|
||||
[0.8, 0.9],
|
||||
],
|
||||
using="colbert",
|
||||
limit=10,
|
||||
)
|
||||
```
|
||||
|
||||
```typescript
|
||||
import { QdrantClient } from "@qdrant/js-client-rest";
|
||||
|
||||
const client = new QdrantClient({ host: "localhost", port: 6333 });
|
||||
|
||||
client.query("{collection_name}", {
|
||||
prefetch: {
|
||||
prefetch: {
|
||||
query: [1, 23, 45, 67],
|
||||
using: 'mrl_byte',
|
||||
limit: 1000
|
||||
},
|
||||
query: [0.01, 0.45, 0.67],
|
||||
using: 'full',
|
||||
limit: 100,
|
||||
},
|
||||
query: [
|
||||
[0.1, 0.2],
|
||||
[0.2, 0.1],
|
||||
[0.8, 0.9],
|
||||
],
|
||||
using: 'colbert',
|
||||
limit: 10,
|
||||
});
|
||||
```
|
||||
|
||||
```rust
|
||||
use qdrant_client::Qdrant;
|
||||
use qdrant_client::qdrant::{PrefetchQueryBuilder, Query, QueryPointsBuilder};
|
||||
@@ -327,7 +443,7 @@ client.query(
|
||||
.add_prefetch(PrefetchQueryBuilder::default()
|
||||
.add_prefetch(PrefetchQueryBuilder::default()
|
||||
.query(Query::new_nearest(vec![1.0, 23.0, 45.0, 67.0]))
|
||||
.using("mlr_byte")
|
||||
.using("mrl_byte")
|
||||
.limit(1000u64)
|
||||
)
|
||||
.query(Query::new_nearest(vec![0.01, 0.45, 0.67]))
|
||||
@@ -363,7 +479,7 @@ client
|
||||
PrefetchQuery.newBuilder()
|
||||
.addPrefetch(
|
||||
PrefetchQuery.newBuilder()
|
||||
.setQuery(nearest(1, 23, 45, 67)) // <------------- small byte vector
|
||||
.setQuery(nearest(1, 23, 45, 67)) // <------------- small byte vector
|
||||
.setUsing("mrl_byte")
|
||||
.setLimit(1000)
|
||||
.build())
|
||||
@@ -374,9 +490,9 @@ client
|
||||
.setQuery(
|
||||
nearest(
|
||||
new float[][] {
|
||||
{0.1f, 0.2f}, // <─┐
|
||||
{0.2f, 0.1f}, // < ├─ multi-vector
|
||||
{0.8f, 0.9f} // < ┘
|
||||
{0.1f, 0.2f}, // <─┐
|
||||
{0.2f, 0.1f}, // < ├─ multi-vector
|
||||
{0.8f, 0.9f} // < ┘
|
||||
}))
|
||||
.setUsing("colbert")
|
||||
.setLimit(10)
|
||||
@@ -418,15 +534,15 @@ await client.QueryAsync(
|
||||
);
|
||||
```
|
||||
|
||||
**Note:** *The multivector feature is not only useful for ColBERT; it can also be used in other ways.*</br>
|
||||
For instance, in e-commerce, you can use multi-vector to store multiple images of the same item. This serves as an alternative to the [group-by](/documentation/concepts/search/#grouping-api) method.
|
||||
|
||||
## Sparse Vectors Compression
|
||||
|
||||
In version 1.9, we introduced the `uint8` [vector datatype](/documentation/concepts/vectors/#datatypes) for sparse vectors, in order to support pre-quantized embeddings from companies like JinaAI and Cohere.
|
||||
This time, we are introducing a new datatype **for both sparse and dense vectors**, as well as a different way of **storing** these vectors.
|
||||
|
||||
**Datatype:** Sparse and dense vectors were previously represented in larger `float32` values, but now they can be turned to the `float16`. `float16` vectors have a lower precision compared to `float32`, which means that there is less numerical accuracy in the vector values - but this is negligible for practical use cases.
|
||||
|
||||
These vectors will use half the memory of regular vectors, which can significantly reduce the footprint of large vector datasets. Operations can be faster due to reduced memory bandwidth requirements and better cache utilization. This can lead to faster vector search operations, especially in memory-bound scenarios.
|
||||
|
||||
@@ -443,6 +559,33 @@ PUT /collections/{collection_name}
|
||||
}
|
||||
```
|
||||
|
||||
```python
|
||||
from qdrant_client import QdrantClient, models
|
||||
|
||||
client = QdrantClient(url="http://localhost:6333")
|
||||
|
||||
client.create_collection(
|
||||
"{collection_name}",
|
||||
vectors_config=models.VectorParams(
|
||||
size=1024, distance=models.Distance.COSINE, datatype=models.Datatype.FLOAT16
|
||||
),
|
||||
)
|
||||
```
|
||||
|
||||
```typescript
|
||||
import { QdrantClient } from "@qdrant/js-client-rest";
|
||||
|
||||
const client = new QdrantClient({ host: "localhost", port: 6333 });
|
||||
|
||||
client.createCollection("{collection_name}", {
|
||||
vectors: {
|
||||
size: 1024,
|
||||
distance: "Cosine",
|
||||
datatype: "float16"
|
||||
}
|
||||
});
|
||||
```
|
||||
|
||||
```java
|
||||
import io.qdrant.client.QdrantClient;
|
||||
import io.qdrant.client.QdrantGrpcClient;
|
||||
@@ -500,7 +643,7 @@ await client.CreateCollectionAsync(
|
||||
);
|
||||
```
|
||||
|
||||
**Storage:** On the backend, we implemented bit packing to minimize the bits needed to store data, crucial for handling sparse vectors in applications like machine learning and data compression. For sparse vectors with mostly zeros, this focuses on storing only the indices and values of non-zero elements.
|
||||
|
||||
You will benefit from a more compact storage and higher processing efficiency. This can also lead to reduced dataset sizes for faster processing and lower storage costs in data compression.
|
||||
|
||||
@@ -525,6 +668,7 @@ documentation, making it easier to navigate and find the information you need.
|
||||
</p>
|
||||
|
||||
## S3 Snapshot Storage
|
||||
|
||||
Qdrant **Collections**, **Shards** and **Storage** can be backed up with [Snapshots](/documentation/concepts/snapshots/) and saved in case of data loss or other data transfer purposes. These snapshots can be quite large and the resources required to maintain them can result in higher costs. AWS S3 and other S3-compatible implementations like [min.io](https://min.io/) is a great low-cost alternative that can hold snapshots without incurring high costs. It is globally reliable, scalable and resistant to data loss.
|
||||
|
||||
You can configure S3 storage settings in the [config.yaml](https://github.com/qdrant/qdrant/blob/master/config/config.yaml), specifically with `snapshots_storage`.
|
||||
@@ -557,7 +701,8 @@ storage:
|
||||
|
||||
This integration allows for a more convenient distribution of snapshots. Users of **any S3-compatible object storage** can now benefit from other platform services, such as automated workflows and disaster recovery options. S3's encryption and access control ensure secure storage and regulatory compliance. Additionally, S3 supports performance optimization through various storage classes and efficient data transfer methods, enabling quick and effective snapshot retrieval and management.
|
||||
|
||||
## Issues API
|
||||
## Issues API
|
||||
|
||||
Issues API notifies you about potential performance issues and misconfigurations. This powerful new feature allows users (such as database admins) to efficiently manage and track issues directly within the system, ensuring smoother operations and quicker resolutions.
|
||||
|
||||
You can find the Issues button in the top right. When you click the bell icon, a sidebar will open to show ongoing issues.
|
||||
@@ -571,4 +716,3 @@ You can find the Issues button in the top right. When you click the bell icon, a
|
||||
- Overwrite global optimizer configuration for collections. Lets you separate roles for indexing and searching within the single qdrant cluster - [#4317](https://github.com/qdrant/qdrant/pull/4317)
|
||||
|
||||
- Delta encoding and bitpacking compression for sparse vectors reduces memory consumption for sparse vectors by up to 75% - [#4253](https://github.com/qdrant/qdrant/pull/4253), [#4350](https://github.com/qdrant/qdrant/pull/4350)
|
||||
|
||||
|
||||
@@ -1,57 +1,26 @@
|
||||
---
|
||||
title: Qdrant Documentation
|
||||
weight: 10
|
||||
hideTOC: true
|
||||
---
|
||||
# Documentation
|
||||
|
||||
**Qdrant (read: quadrant)** is a vector similarity search engine. Use our documentation to develop a production-ready service with a convenient API to store, search, and manage vectors with an additional payload. Qdrant's expanding features allow for all sorts of neural network or semantic-based matching, faceted search, and other applications.
|
||||
Qdrant is an AI-native vector dabatase and a semantic search engine. You can use it to extract meaningful information from unstructured data. **[Learn more about vector search](/documentation/overview/)** and how it works with AI.
|
||||
|
||||
## Product Release: Announcing Qdrant Hybrid Cloud!
|
||||
***<p style="text-align: center;">Now you can attach your own infrastructure to Qdrant Cloud!</p>***
|
||||
|||
|
||||
|-:|:-|
|
||||
|[Docker Quickstart](/documentation/quick-start/)|[Cloud Quickstart](/documentation/cloud/quickstart-cloud/)|
|
||||
|Use Qdrant Client SDKs|Try the GUI Dashboard|
|
||||
|
||||
[](https://qdrant.to/cloud)
|
||||
## Ready to start developing?
|
||||
|
||||
Use [**Qdrant Hybrid Cloud**](/hybrid-cloud/) to build the best private environment that suits your needs. Manage your own clusters via the [Qdrant Cloud UI](/documentation/cloud/), but continue to run them within your own private infrastructure for complete security and sovereignty.
|
||||
***<p style="text-align: center;">Qdrant is open-source and can be self-hosted. However, the quickest way to get started is with our [free tier](https://qdrant.to/cloud) on Qdrant Cloud. It scales easily and provides an UI where you can interact with data.</p>***
|
||||
|
||||
## First-Time Users:
|
||||
[](https://qdrant.to/cloud)
|
||||
|
||||
There are three ways to use Qdrant:
|
||||
|
||||
1. [**Run a Docker image**](quick-start/) if you don't have a Python development environment. Setup a local Qdrant server and storage in a few moments.
|
||||
2. [**Get the Python client**](https://github.com/qdrant/qdrant-client) if you're familiar with Python. Just `pip install qdrant-client`. The client also supports an in-memory database.
|
||||
3. [**Spin up a Qdrant Cloud cluster:**](cloud/) the recommended method to run Qdrant in production. Read [Quickstart](cloud/quickstart-cloud/) to setup your first instance.
|
||||
|
||||
### Recommended Workflow:
|
||||
|
||||
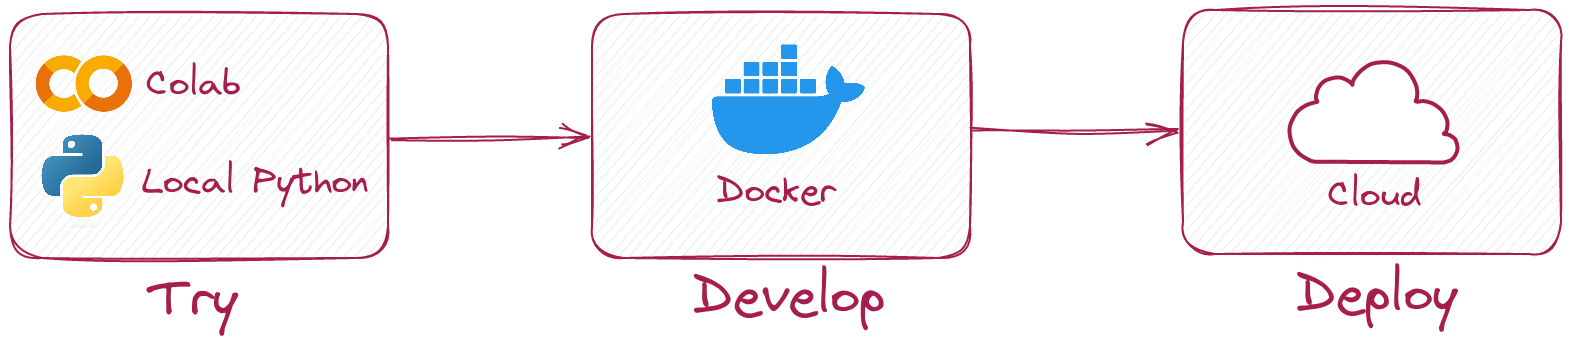
|
||||
|
||||
First, try Qdrant locally using the [Qdrant Client](https://github.com/qdrant/qdrant-client) and with the help of our [Tutorials](tutorials/) and Guides. Develop a sample app from our [Examples](examples/) list and try it using a [Qdrant Docker](guides/installation/) container. Then, when you are ready for production, deploy to a Free Tier [Qdrant Cloud](cloud/) cluster.
|
||||
|
||||
### Try Qdrant with Practice Data:
|
||||
|
||||
You may always use our [Practice Datasets](datasets/) to build with Qdrant. This page will be regularly updated with dataset snapshots you can use to bootstrap complete projects.
|
||||
|
||||
## Popular Topics:
|
||||
|
||||
| Tutorial | Description | Tutorial| Description |
|
||||
|----------------------------------------------------|----------------------------------------------|---------|------------------|
|
||||
| [Installation](guides/installation/) | Different ways to install Qdrant. | [Collections](concepts/collections/) | Learn about the central concept behind Qdrant. |
|
||||
| [Configuration](guides/configuration/) | Update the default configuration. | [Bulk Upload](tutorials/bulk-upload/) | Efficiently upload a large number of vectors. |
|
||||
| [Optimization](tutorials/optimize/) | Optimize Qdrant's resource usage. | [Multitenancy](tutorials/multiple-partitions/) | Setup Qdrant for multiple independent users. |
|
||||
|
||||
## Common Use Cases:
|
||||
|
||||
Qdrant is ideal for deploying applications based on the matching of embeddings produced by neural network encoders. Check out the [Examples](examples/) section to learn more about common use cases. Also, you can visit the [Tutorials](tutorials/) page to learn how to work with Qdrant in different ways.
|
||||
|
||||
| Use Case | Description | Stack |
|
||||
|-----------------------|----------------------------------------------|--------|
|
||||
| [Semantic Search for Beginners](tutorials/search-beginners/) | Build a search engine locally with our most basic instruction set. | Qdrant |
|
||||
| [Build a Simple Neural Search](tutorials/neural-search/) | Build and deploy a neural search. [Check out the live demo app.](https://demo.qdrant.tech/#/) | Qdrant, BERT, FastAPI |
|
||||
| [Build a Search with Aleph Alpha](tutorials/aleph-alpha-search/) | Build a simple semantic search that combines text and image data. | Qdrant, Aleph Alpha |
|
||||
| [Developing Recommendations Systems](https://githubtocolab.com/qdrant/examples/blob/master/qdrant_101_getting_started/getting_started.ipynb) | Learn how to get started building semantic search and recommendation systems. | Qdrant |
|
||||
| [Search and Recommend Newspaper Articles](https://githubtocolab.com/qdrant/examples/blob/master/qdrant_101_text_data/qdrant_and_text_data.ipynb) | Work with text data to develop a semantic search and a recommendation engine for news articles. | Qdrant |
|
||||
| [Recommendation System for Songs](https://githubtocolab.com/qdrant/examples/blob/master/qdrant_101_audio_data/03_qdrant_101_audio.ipynb) | Use Qdrant to develop a music recommendation engine based on audio embeddings. | Qdrant |
|
||||
| [Image Comparison System for Skin Conditions](https://colab.research.google.com/github/qdrant/examples/blob/master/qdrant_101_image_data/04_qdrant_101_cv.ipynb) | Use Qdrant to compare challenging images with labels representing different skin diseases. | Qdrant |
|
||||
| [Question and Answer System with LlamaIndex](https://githubtocolab.com/qdrant/examples/blob/master/llama_index_recency/Qdrant%20and%20LlamaIndex%20%E2%80%94%20A%20new%20way%20to%20keep%20your%20Q%26A%20systems%20up-to-date.ipynb) | Combine Qdrant and LlamaIndex to create a self-updating Q&A system. | Qdrant, LlamaIndex, Cohere |
|
||||
| [Extractive QA System](https://githubtocolab.com/qdrant/examples/blob/master/extractive_qa/extractive-question-answering.ipynb) | Extract answers directly from context to generate highly relevant answers. | Qdrant |
|
||||
| [Ecommerce Reverse Image Search](https://githubtocolab.com/qdrant/examples/blob/master/ecommerce_reverse_image_search/ecommerce-reverse-image-search.ipynb) | Accept images as search queries to receive semantically appropriate answers. | Qdrant |
|
||||
## Qdrant's most popular features:
|
||||
||||
|
||||
|:-|:-|:-|
|
||||
|[Filtrable HNSW](/documentation/filtering/) </br> Single-stage payload filtering | [Recommendations & Context Search](/documentation/concepts/explore/#explore-the-data) </br> Exploratory advanced search| [Pure-Vector Hybrid Search](/documentation/hybrid-queries/)</br>Full text and semantic search in one|
|
||||
|[Multitenancy](/documentation/guides/multiple-partitions/) </br> Payload-based partitioning|[Custom Sharding](/documentation/guides/distributed_deployment/#sharding) </br> For data isolation and distribution|[Role Based Access Control](/documentation/guides/security/?q=jwt#granular-access-control-with-jwt)</br>Secure JWT-based access |
|
||||
|[Quantization](/documentation/guides/quantization/) </br> Compress data for drastic speedups|[Multivector Support](/documentation/concepts/vectors/?q=multivect#multivectors) </br> For ColBERT late interaction |[Built-in IDF](/documentation/concepts/indexing/?q=inverse+docu#idf-modifier) </br> Cutting-edge similarity calculation|
|
||||
@@ -1748,8 +1748,6 @@ new OrderBy
|
||||
};
|
||||
```
|
||||
|
||||
**Note:** for payloads with more than one value (such as arrays), the same point may show up more than once. Each point can appear as many times as the number of elements in the array. For example, if you have a point payload with a `timestamp` key, and the value for the key is an array of 3 elements, the same point will appear 3 times in the results, one for each timestamp.
|
||||
|
||||
<aside role="alert">When you use the <code>order_by</code> parameter, pagination is disabled.</aside>
|
||||
|
||||
When sorting is based on a non-unique value, it is not possible to rely on an ID offset. Thus, next_page_offset is not returned within the response. However, you can still do pagination by combining `"order_by": { "start_from": ... }` with a `{ "must_not": [{ "has_id": [...] }] }` filter.
|
||||
|
||||
@@ -2,7 +2,7 @@
|
||||
title: Vectors
|
||||
weight: 41
|
||||
aliases:
|
||||
- ../vectors
|
||||
- /vectors
|
||||
---
|
||||
|
||||
|
||||
@@ -19,7 +19,7 @@ If two images are similar, their vectors will be close to each other in the vect
|
||||
In order to obtain a vector representation of an object, you need to apply a vectorization algorithm to the object.
|
||||
Usually, this algorithm is a neural network that converts the object into a fixed-size vector.
|
||||
|
||||
The neural network is usually [trained](../articles/metric-learning-tips/) on a pairs or [triplets](../articles/triplet-loss/) of similar and dissimilar objects, so it learns to recognize a specific type of similarity.
|
||||
The neural network is usually [trained](/articles/metric-learning-tips/) on a pairs or [triplets](/articles/triplet-loss/) of similar and dissimilar objects, so it learns to recognize a specific type of similarity.
|
||||
|
||||
By using this property of vectors, you can explore your data in a number of ways; e.g. by searching for similar objects, clustering objects, and more.
|
||||
|
||||
@@ -58,7 +58,7 @@ It looks like this:
|
||||
```
|
||||
|
||||
The majority of neural networks create dense vectors, so you can use them with Qdrant without any additional processing.
|
||||
Although compatible with most embedding models out there, Qdrant has been tested with the following [verified embedding providers](../embeddings/).
|
||||
Although compatible with most embedding models out there, Qdrant has been tested with the following [verified embedding providers](/documentation/embeddings/).
|
||||
|
||||
### Sparse Vectors
|
||||
|
||||
@@ -1313,16 +1313,16 @@ await client.CreateCollectionAsync(
|
||||
## Quantization
|
||||
|
||||
Apart from changing the datatype of the original vectors, Qdrant can create quantized representations of vectors alongside the original ones.
|
||||
This quantized representation can be used to quickly select candidates for rescoring with the original vectors, or even used directly for search.
|
||||
This quantized representation can be used to quickly select candidates for rescoring with the original vectors or even used directly for search.
|
||||
|
||||
Quantization is applied in the background, during the optimization process.
|
||||
|
||||
More information about the quantization process can be found in the [Quantization](../guides/quantization/) section.
|
||||
More information about the quantization process can be found in the [Quantization](/documentation/guides/quantization/) section.
|
||||
|
||||
|
||||
## Vector Storage
|
||||
|
||||
Depending on the requirements of the application, Qdrant can use one of the data storage options.
|
||||
Keep in mind that youu will have to tradeoff between search speed and the size of RAM used.
|
||||
Keep in mind that you will have to tradeoff between search speed and the size of RAM used.
|
||||
|
||||
More information about the storage options can be found in the [Storage](../concepts/storage/#vector-storage) section.
|
||||
More information about the storage options can be found in the [Storage](/documentation/concepts/storage/#vector-storage) section.
|
||||
|
||||
@@ -65,7 +65,7 @@ from fastembed import TextEmbedding, SparseTextEmbedding
|
||||
def vectorize(partition_data):
|
||||
# Initialize dense and sparse models
|
||||
dense_model = TextEmbedding(model_name="BAAI/bge-small-en-v1.5")
|
||||
sparse_model = SparseTextEmbedding(model_name="prithivida/Splade_PP_en_v1")
|
||||
sparse_model = SparseTextEmbedding(model_name="Qdrant/bm25")
|
||||
|
||||
for row in partition_data:
|
||||
# Generate dense and sparse vectors
|
||||
@@ -81,7 +81,7 @@ def vectorize(partition_data):
|
||||
]
|
||||
```
|
||||
|
||||
We're using the [BAAI/bge-small-en-v1.5](https://huggingface.co/BAAI/bge-small-en-v1.5) model for dense embeddings and [prithivida/Splade_PP_en_v1](https://huggingface.co/prithivida/Splade_PP_en_v1) for sparse embeddings.
|
||||
We're using the [BAAI/bge-small-en-v1.5](https://huggingface.co/BAAI/bge-small-en-v1.5) model for dense embeddings and [BM25](https://huggingface.co/Qdrant/bm25) for sparse embeddings.
|
||||
|
||||
#### Applying the UDF on our dataframe
|
||||
|
||||
|
||||
@@ -42,7 +42,7 @@ This command generates all of the project files you need to run Airflow locally.
|
||||
To use Qdrant within Airflow, install the Qdrant Airflow provider by adding the following to the `requirements.txt` file
|
||||
|
||||
```text
|
||||
apache-airflow-providers-qdrant==1.1.0
|
||||
apache-airflow-providers-qdrant
|
||||
```
|
||||
|
||||
### Configure credentials
|
||||
@@ -178,12 +178,12 @@ def recommend_book():
|
||||
) -> None:
|
||||
hook = QdrantHook(conn_id=QDRANT_CONNECTION_ID)
|
||||
|
||||
result = hook.conn.search(
|
||||
result = hook.conn.query_points(
|
||||
collection_name=COLLECTION_NAME,
|
||||
query_vector=preference_embedding,
|
||||
query=preference_embedding,
|
||||
limit=1,
|
||||
with_payload=True,
|
||||
)
|
||||
).points
|
||||
|
||||
print("Book recommendation: " + result[0].payload["title"])
|
||||
print("Description: " + result[0].payload["description"])
|
||||
|
||||
@@ -1,28 +1,28 @@
|
||||
---
|
||||
title: Database Optimization
|
||||
weight: 3
|
||||
weight: 2
|
||||
---
|
||||
|
||||
## Database Optimization Strategies
|
||||
# Frequently Asked Questions: Database Optimization
|
||||
|
||||
### How do I reduce memory usage?
|
||||
|
||||
The primary source of memory usage vector data. There are several ways to address that:
|
||||
The primary source of memory usage is vector data. There are several ways to address that:
|
||||
|
||||
- Configure [Quantization](../../guides/quantization/) to reduce the memory usage of vectors.
|
||||
- Configure on-disk vector storage
|
||||
|
||||
The choice of the approach depends on your requirements.
|
||||
Read more about [configuring the optimal](../../tutorials/optimize/) use of Qdrant.
|
||||
The choice of the approach depends on your requirements.
|
||||
Read more about [configuring the optimal](../../tutorials/optimize/) use of Qdrant.
|
||||
|
||||
### How do you choose machine configuration?
|
||||
### How do you choose the machine configuration?
|
||||
|
||||
There are two main scenarios of Qdrant usage in terms of resource consumption:
|
||||
|
||||
- **Performance-optimized** -- when you need to serve vector search as fast (many) as possible. In this case, you need to have as much vector data in RAM as possible. Use our [calculator](https://cloud.qdrant.io/calculator) to estimate the required RAM.
|
||||
- **Storage-optimized** -- when you need to store many vectors and minimize costs by compromising some search speed. In this case, pay attention to the disk speed instead. More about it in the article about [Memory Consumption](../../../articles/memory-consumption/).
|
||||
|
||||
### I configured on-disk vector storage, but memory usage is still high. Why?
|
||||
### I configured on-disk vector storage, but memory usage is still high. Why?
|
||||
|
||||
Firstly, memory usage metrics as reported by `top` or `htop` may be misleading. They are not showing the minimal amount of memory required to run the service.
|
||||
If the RSS memory usage is 10 GB, it doesn't mean that it won't work on a machine with 8 GB of RAM.
|
||||
@@ -34,11 +34,10 @@ As a result, the Qdrant process might use more memory than the minimum required
|
||||
|
||||
If you want to limit the memory usage of the service, we recommend using [limits in Docker](https://docs.docker.com/config/containers/resource_constraints/#memory) or Kubernetes.
|
||||
|
||||
|
||||
### My requests are very slow or time out. What should I do?
|
||||
|
||||
There are several possible reasons for that:
|
||||
|
||||
- **Using filters without payload index** -- If you're performing a search with a filter but you don't have a payload index, Qdrant will have to load whole payload data from disk to check the filtering condition. Ensure you have adequately configured [payload indexes](../../concepts/indexing/#payload-index).
|
||||
- **Usage of on-disk vector storage with slow disks** -- If you're using on-disk vector storage, ensure you have fast enough disks. We recommend using local SSDs with at least 50k IOPS. Read more about the influence of the disk speed on the search latency in the article about [Memory Consumption](../../../articles/memory-consumption/).
|
||||
- **Large limit or non-optimal query parameters** -- A large limit or offset might lead to significant performance degradation. Please pay close attention to the query/collection parameters that significantly diverge from the defaults. They might be the reason for the performance issues.
|
||||
- **Large limit or non-optimal query parameters** -- A large limit or offset might lead to significant performance degradation. Please pay close attention to the query/collection parameters that significantly diverge from the defaults. They might be the reason for the performance issues.
|
||||
@@ -1,18 +1,48 @@
|
||||
---
|
||||
title: Fundamentals
|
||||
title: Qdrant Fundamentals
|
||||
weight: 1
|
||||
---
|
||||
|
||||
## Qdrant Fundamentals
|
||||
# Frequently Asked Questions: General Topics
|
||||
||||||
|
||||
|-|-|-|-|-|
|
||||
|[Vectors](/documentation/faq/qdrant-fundamentals/#vectors)|[Search](/documentation/faq/qdrant-fundamentals/#search)|[Collections](/documentation/faq/qdrant-fundamentals/#collections)|[Compatibility](/documentation/faq/qdrant-fundamentals/#compatibility)|[Cloud](/documentation/faq/qdrant-fundamentals/#cloud)|
|
||||
|
||||
### How many collections can I create?
|
||||
## Vectors
|
||||
|
||||
As much as you want, but be aware that each collection requires additional resources.
|
||||
It is _highly_ recommended not to create many small collections, as it will lead to significant resource consumption overhead.
|
||||
### What is the maximum vector dimension supported by Qdrant?
|
||||
|
||||
We consider creating a collection for each user/dialog/document as an antipattern.
|
||||
Qdrant supports up to 65,535 dimensions by default, but this can be configured to support higher dimensions.
|
||||
|
||||
Please read more about collections, isolation, and multiple users in our [Multitenancy](../../tutorials/multiple-partitions/) tutorial.
|
||||
### What is the maximum size of vector metadata that can be stored?
|
||||
|
||||
There is no inherent limitation on metadata size, but it should be [optimized for performance and resource usage](/documentation/guides/optimize/). Users can set upper limits in the configuration.
|
||||
|
||||
### Can the same similarity search query yield different results on different machines?
|
||||
|
||||
Yes, due to differences in hardware configurations and parallel processing, results may vary slightly.
|
||||
|
||||
### What to do with documents with small chunks using a fixed chunk strategy?
|
||||
|
||||
For documents with small chunks, consider merging chunks or using variable chunk sizes to optimize vector representation and search performance.
|
||||
|
||||
### How do I choose the right vector embeddings for my use case?
|
||||
|
||||
This depends on the nature of your data and the specific application. Consider factors like dimensionality, domain-specific models, and the performance characteristics of different embeddings.
|
||||
|
||||
### How does Qdrant handle different vector embeddings from various providers in the same collection?
|
||||
|
||||
Qdrant natively [supports multiple vectors per data point](/documentation/concepts/vectors/#multivectors), allowing different embeddings from various providers to coexist within the same collection.
|
||||
|
||||
### Can I migrate my embeddings from another vector store to Qdrant?
|
||||
|
||||
Yes, Qdrant supports migration of embeddings from other vector stores, facilitating easy transitions and adoption of Qdrant’s features.
|
||||
|
||||
## Search
|
||||
|
||||
### How does Qdrant handle real-time data updates and search?
|
||||
|
||||
Qdrant supports live updates for vector data, with newly inserted, updated and deleted vectors available for immediate search. The system uses full-scan search on unindexed segments during background index updates.
|
||||
|
||||
### My search results contain vectors with null values. Why?
|
||||
|
||||
@@ -36,11 +66,8 @@ What Qdrant can do:
|
||||
- Apply full-text filters to the vector search (i.e., perform vector search among the records with specific words or phrases)
|
||||
- Do prefix search and semantic [search-as-you-type](../../../articles/search-as-you-type/)
|
||||
- Sparse vectors, as used in [SPLADE](https://github.com/naver/splade) or similar models
|
||||
|
||||
What Qdrant plans to introduce in the future:
|
||||
|
||||
- ColBERT and other late-interaction models
|
||||
- Fusion of the multiple searches
|
||||
- [Multi-vectors](../../concepts/vectors/#multivectors), for example ColBERT and other late-interaction models
|
||||
- Combination of the [multiple searches](../../concepts/hybrid-queries/)
|
||||
|
||||
What Qdrant doesn't plan to support:
|
||||
|
||||
@@ -51,6 +78,17 @@ What Qdrant doesn't plan to support:
|
||||
Of course, you can always combine Qdrant with any specialized tool you need, including full-text search engines.
|
||||
Read more about [our approach](../../../articles/hybrid-search/) to hybrid search.
|
||||
|
||||
## Collections
|
||||
|
||||
### How many collections can I create?
|
||||
|
||||
As many as you want, but be aware that each collection requires additional resources.
|
||||
It is _highly_ recommended not to create many small collections, as it will lead to significant resource consumption overhead.
|
||||
|
||||
We consider creating a collection for each user/dialog/document as an antipattern.
|
||||
|
||||
Please read more about collections, isolation, and multiple users in our [Multitenancy](../../tutorials/multiple-partitions/) tutorial.
|
||||
|
||||
### How do I upload a large number of vectors into a Qdrant collection?
|
||||
|
||||
Read about our recommendations in the [bulk upload](../../tutorials/bulk-upload/) tutorial.
|
||||
@@ -59,14 +97,16 @@ Read about our recommendations in the [bulk upload](../../tutorials/bulk-upload/
|
||||
|
||||
No, Qdrant requires full precision vectors for operations like reindexing, rescoring, etc.
|
||||
|
||||
## Qdrant Cloud
|
||||
## Compatibility
|
||||
|
||||
### Is it possible to scale down a Qdrant Cloud cluster?
|
||||
### Is Qdrant compatible with CPUs or GPUs for vector computation?
|
||||
|
||||
In general, no. There's no way to scale down the underlying disk storage.
|
||||
But in some cases, we might be able to help you with that through manual intervention, but it's not guaranteed.
|
||||
Qdrant primarily relies on CPU acceleration for scalability and efficiency, with no current support for GPU acceleration.
|
||||
|
||||
## Versioning
|
||||
### Do you guarantee compatibility across versions?
|
||||
|
||||
In case your version is older, we only guarantee compatibility between two consecutive minor versions. This also applies to client versions. Ensure your client version is never more than one minor version away from your cluster version.
|
||||
While we will assist with break/fix troubleshooting of issues and errors specific to our products, Qdrant is not accountable for reviewing, writing (or rewriting), or debugging custom code.
|
||||
|
||||
### Do you support downgrades?
|
||||
|
||||
@@ -77,7 +117,9 @@ data is automatically migrated to the newer storage format. This migration is no
|
||||
|
||||
We only guarantee compatibility if you update between consecutive versions. You would need to upgrade versions one at a time: `1.1 -> 1.2`, then `1.2 -> 1.3`, then `1.3 -> 1.4`.
|
||||
|
||||
### Do you guarantee compatibility across versions?
|
||||
## Cloud
|
||||
|
||||
In case your version is older, we only guarantee compatibility between two consecutive minor versions. This also applies to client versions. Ensure your client version is never more than one minor version away from your cluster version.
|
||||
While we will assist with break/fix troubleshooting of issues and errors specific to our products, Qdrant is not accountable for reviewing, writing (or rewriting), or debugging custom code.
|
||||
### Is it possible to scale down a Qdrant Cloud cluster?
|
||||
|
||||
In general, no. There's no way to scale down the underlying disk storage.
|
||||
But in some cases, we might be able to help you with that through manual intervention, but it's not guaranteed.
|
||||
|
||||
@@ -32,7 +32,8 @@ weight: 33
|
||||
| [OpenLIT](./openlit/) | Platform for OpenTelemetry-native Observability & Evals for LLMs and Vector Databases. |
|
||||
| [OpenLLMetry](./openllmetry/) | Set of OpenTelemetry extensions to add Observability for your LLM application. |
|
||||
| [Pandas-AI](./pandas-ai/) | Python library to query/visualize your data (CSV, XLSX, PostgreSQL, etc.) in natural language |
|
||||
| [Pipedream](./pipedream/) | Platform for connecting apps and developing event-driven automations. |
|
||||
| [Pipedream](./pipedream/) | Platform for connecting apps and developing event-driven automation. |
|
||||
| [Portable.io](./portable/) | Cloud platform for developing and deploying ELT transformations. |
|
||||
| [PrivateGPT](./privategpt/) | Tool to ask questions about your documents using local LLMs emphasising privacy. |
|
||||
| [Rivet](./rivet/) | A visual programming environment for building AI agents with LLMs. |
|
||||
| [Semantic Router](./semantic-router/) | Python library to build a decision-making layer for AI applications using vector search. |
|
||||
|
||||
@@ -27,39 +27,42 @@ Before you use the following code sample, customize the following values for you
|
||||
list collections.
|
||||
|
||||
```go
|
||||
import (
|
||||
"fmt"
|
||||
"log"
|
||||
package main
|
||||
|
||||
"github.com/tmc/langchaingo/embeddings"
|
||||
"github.com/tmc/langchaingo/llms/openai"
|
||||
"github.com/tmc/langchaingo/vectorstores"
|
||||
"github.com/tmc/langchaingo/vectorstores/qdrant"
|
||||
import (
|
||||
"log"
|
||||
"net/url"
|
||||
|
||||
"github.com/tmc/langchaingo/embeddings"
|
||||
"github.com/tmc/langchaingo/llms/openai"
|
||||
"github.com/tmc/langchaingo/vectorstores/qdrant"
|
||||
)
|
||||
|
||||
llm, err := openai.New()
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
func main() {
|
||||
llm, err := openai.New()
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
|
||||
e, err := embeddings.NewEmbedder(llm)
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
e, err := embeddings.NewEmbedder(llm)
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
|
||||
url, err := url.Parse("YOUR_QDRANT_REST_URL")
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
url, err := url.Parse("YOUR_QDRANT_REST_URL")
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
|
||||
store, err := qdrant.New(
|
||||
qdrant.WithURL(*url),
|
||||
qdrant.WithCollectionName("YOUR_COLLECTION_NAME"),
|
||||
qdrant.WithEmbedder(e),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
store, err := qdrant.New(
|
||||
qdrant.WithURL(*url),
|
||||
qdrant.WithCollectionName("YOUR_COLLECTION_NAME"),
|
||||
qdrant.WithEmbedder(e),
|
||||
)
|
||||
if err != nil {
|
||||
log.Fatal(err)
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Further Reading
|
||||
|
||||
@@ -9,35 +9,37 @@ aliases:
|
||||
# Langchain
|
||||
|
||||
Langchain is a library that makes developing Large Language Model-based applications much easier. It unifies the interfaces
|
||||
to different libraries, including major embedding providers and Qdrant. Using Langchain, you can focus on the business value
|
||||
instead of writing the boilerplate.
|
||||
to different libraries, including major embedding providers and Qdrant. Using Langchain, you can focus on the business value instead of writing the boilerplate.
|
||||
|
||||
Langchain distributes their Qdrant integration in their community package. It might be installed with pip:
|
||||
Langchain distributes the Qdrant integration as a partner package.
|
||||
|
||||
It might be installed with pip:
|
||||
|
||||
```bash
|
||||
pip install langchain-community langchain-qdrant
|
||||
pip install langchain-qdrant
|
||||
```
|
||||
|
||||
Qdrant acts as a vector index that may store the embeddings with the documents used to generate them. There are various ways to use it, but calling `Qdrant.from_texts` or `Qdrant.from_documents` is probably the most straightforward way to get started:
|
||||
The integration supports searching for relevant documents usin dense/sparse and hybrid retrieval.
|
||||
|
||||
Qdrant acts as a vector index that may store the embeddings with the documents used to generate them. There are various ways to use it, but calling `QdrantVectorStore.from_texts` or `QdrantVectorStore.from_documents` is probably the most straightforward way to get started:
|
||||
|
||||
```python
|
||||
from langchain_qdrant import Qdrant
|
||||
from langchain_community.embeddings.huggingface import HuggingFaceEmbeddings
|
||||
from langchain_qdrant import QdrantVectorStore
|
||||
from langchain_openai import OpenAIEmbeddings
|
||||
|
||||
embeddings = HuggingFaceEmbeddings(
|
||||
model_name="sentence-transformers/all-mpnet-base-v2"
|
||||
)
|
||||
doc_store = Qdrant.from_texts(
|
||||
embeddings = OpenAIEmbeddings()
|
||||
|
||||
doc_store = QdrantVectorStore.from_texts(
|
||||
texts, embeddings, url="<qdrant-url>", api_key="<qdrant-api-key>", collection_name="texts"
|
||||
)
|
||||
```
|
||||
|
||||
## Using an existing collection
|
||||
|
||||
To get an instance of `langchain_qdrant.Qdrant` without loading any new documents or texts, you can use the `Qdrant.from_existing_collection()` method.
|
||||
To get an instance of `langchain_qdrant.QdrantVectorStore` without loading any new documents or texts, you can use the `QdrantVectorStore.from_existing_collection()` method.
|
||||
|
||||
```python
|
||||
doc_store = Qdrant.from_existing_collection(
|
||||
doc_store = QdrantVectorStore.from_existing_collection(
|
||||
embeddings=embeddings,
|
||||
collection_name="my_documents",
|
||||
url="<qdrant-url>",
|
||||
@@ -57,7 +59,7 @@ For some testing scenarios and quick experiments, you may prefer to keep all the
|
||||
client is destroyed - usually at the end of your script/notebook.
|
||||
|
||||
```python
|
||||
qdrant = Qdrant.from_documents(
|
||||
qdrant = QdrantVectorStore.from_documents(
|
||||
docs,
|
||||
embeddings,
|
||||
location=":memory:", # Local mode with in-memory storage only
|
||||
@@ -80,13 +82,13 @@ qdrant = Qdrant.from_documents(
|
||||
|
||||
### On-premise server deployment
|
||||
|
||||
No matter if you choose to launch Qdrant locally with [a Docker container](/documentation/guides/installation/), or
|
||||
No matter if you choose to launch QdrantVectorStore locally with [a Docker container](/documentation/guides/installation/), or
|
||||
select a Kubernetes deployment with [the official Helm chart](https://github.com/qdrant/qdrant-helm), the way you're
|
||||
going to connect to such an instance will be identical. You'll need to provide a URL pointing to the service.
|
||||
|
||||
```python
|
||||
url = "<---qdrant url here --->"
|
||||
qdrant = Qdrant.from_documents(
|
||||
qdrant = QdrantVectorStore.from_documents(
|
||||
docs,
|
||||
embeddings,
|
||||
url,
|
||||
@@ -95,6 +97,78 @@ qdrant = Qdrant.from_documents(
|
||||
)
|
||||
```
|
||||
|
||||
## Similarity search
|
||||
|
||||
`QdrantVectorStore` supports 3 modes for similarity searches. They can be configured using the `retrieval_mode` parameter when setting up the class.
|
||||
|
||||
- Dense Vector Search(Default)
|
||||
- Sparse Vector Search
|
||||
- Hybrid Search
|
||||
|
||||
### Dense Vector Search
|
||||
|
||||
To search with only dense vectors,
|
||||
|
||||
- The `retrieval_mode` parameter should be set to `RetrievalMode.DENSE`(default).
|
||||
- A [dense embeddings](https://python.langchain.com/v0.2/docs/integrations/text_embedding/) value should be provided for the `embedding` parameter.
|
||||
|
||||
```py
|
||||
from langchain_qdrant import RetrievalMode
|
||||
|
||||
qdrant = QdrantVectorStore.from_documents(
|
||||
docs,
|
||||
embedding=embeddings,
|
||||
location=":memory:",
|
||||
collection_name="my_documents",
|
||||
retrieval_mode=RetrievalMode.DENSE,
|
||||
)
|
||||
|
||||
query = "What did the president say about Ketanji Brown Jackson"
|
||||
found_docs = qdrant.similarity_search(query)
|
||||
```
|
||||
|
||||
### Sparse Vector Search
|
||||
|
||||
To search with only sparse vectors,
|
||||
|
||||
- The `retrieval_mode` parameter should be set to `RetrievalMode.SPARSE`.
|
||||
- An implementation of the [SparseEmbeddings interface](https://github.com/langchain-ai/langchain/blob/master/libs/partners/qdrant/langchain_qdrant/sparse_embeddings.py) using any sparse embeddings provider has to be provided as value to the `sparse_embedding` parameter.
|
||||
|
||||
The `langchain-qdrant` package provides a [FastEmbed](https://github.com/qdrant/fastembed) based implementation out of the box.
|
||||
|
||||
To use it, install the FastEmbed package.
|
||||
|
||||
```sh
|
||||
pip install fastembed
|
||||
```
|
||||
|
||||
```python
|
||||
from langchain_qdrant import FastEmbedSparse, RetrievalMode
|
||||
|
||||
sparse_embeddings = FastEmbedSparse(model_name="Qdrant/BM25")
|
||||
|
||||
qdrant = QdrantVectorStore.from_documents(
|
||||
docs,
|
||||
sparse_embedding=sparse_embeddings,
|
||||
location=":memory:",
|
||||
collection_name="my_documents",
|
||||
retrieval_mode=RetrievalMode.SPARSE,
|
||||
)
|
||||
|
||||
query = "What did the president say about Ketanji Brown Jackson"
|
||||
found_docs = qdrant.similarity_search(query)
|
||||
```
|
||||
|
||||
### Hybrid Vector Search
|
||||
|
||||
To perform a hybrid search using dense and sparse vectors with score fusion,
|
||||
|
||||
- The `retrieval_mode` parameter should be set to `RetrievalMode.HYBRID`.
|
||||
- A [dense embeddings](https://python.langchain.com/v0.2/docs/integrations/text_embedding/) value should be provided for the `embedding` parameter.
|
||||
- An implementation of the [SparseEmbeddings interface](https://github.com/langchain-ai/langchain/blob/master/libs/partners/qdrant/langchain_qdrant/sparse_embeddings.py) using any sparse embeddings provider has to be provided as value to the `sparse_embedding` parameter.
|
||||
|
||||
Note that if you've added documents with the HYBRID mode, you can switch to any retrieval mode when searching. Since both the dense and sparse vectors are available in the collection.
|
||||
|
||||
## Next steps
|
||||
|
||||
If you'd like to know more about running Qdrant in a Langchain-based application, please read our article
|
||||
|
||||
@@ -30,4 +30,4 @@ The `Query Qdrant` processor can perform a similarity search across a Qdrant col
|
||||
## Further Reading
|
||||
|
||||
- [NiFi Documentation](https://nifi.apache.org/documentation/v2/).
|
||||
- [Source Code](https://github.com/apache/nifi/tree/main/nifi-python-extensions/nifi-text-embeddings-module/src/main/python)
|
||||
- [Source Code](https://github.com/apache/nifi-python-extensions)
|
||||
|
||||
@@ -0,0 +1,34 @@
|
||||
---
|
||||
title: Portable.io
|
||||
weight: 3700
|
||||
---
|
||||
|
||||
# Portable
|
||||
|
||||
[Portable](https://portable.io/) is an ELT platform that builds connectors on-demand for data teams. It enables connecting applications to your data warehouse with no code.
|
||||
|
||||
You can avail the [Qdrant connector](https://portable.io/connectors/qdrant) to build data pipelines from your collections.
|
||||
|
||||

|
||||
|
||||
## Prerequisites
|
||||
|
||||
1. A Qdrant instance to connect to. You can get a free cloud instance at [cloud.qdrant.io](https://cloud.qdrant.io/).
|
||||
2. A [Portable account](https://app.portable.io/).
|
||||
|
||||
## Setting up the connector
|
||||
|
||||
Navigate to the Portable dashboard. Search for `"Qdrant"` in the sources section.
|
||||
|
||||

|
||||
|
||||
Configure the connector with your Qdrant instance credentials.
|
||||
|
||||

|
||||
|
||||
You can now build your flows using data from Qdrant by selecting a [destination](https://app.portable.io/destinations) and scheduling it.
|
||||
|
||||
## Further Reading
|
||||
|
||||
- [Portable API Reference](https://developer.portable.io/api-reference/introduction).
|
||||
- [Portable Academy](https://portable.io/learn)
|
||||
@@ -134,7 +134,7 @@ Both API keys can be used simultaneously.
|
||||
|
||||
*Available as of v1.9.0*
|
||||
|
||||
For more complex cases, Qdrant supports granular access control with [JSON Web Tokens (JWT)](https://jwt.io/).
|
||||
For more complex cases, Qdrant supports granular access control with [JSON Web Tokens (JWT)](https://jwt.io/).
|
||||
This allows you to have tokens, which allow restricited access to a specific parts of the stored data and build [Role-based access control (RBAC)](https://en.wikipedia.org/wiki/Role-based_access_control) on top of that.
|
||||
In this way, you can define permissions for users and restrict access to sensitive endpoints.
|
||||
|
||||
@@ -149,7 +149,7 @@ service:
|
||||
Or with the environment variables:
|
||||
|
||||
```bash
|
||||
export QDRANT__SERVICE__API_KEY=your_secret_api_key_here
|
||||
export QDRANT__SERVICE__API_KEY=your_secret_api_key_here
|
||||
export QDRANT__SERVICE__JWT_RBAC=true
|
||||
```
|
||||
|
||||
@@ -266,7 +266,7 @@ These are the available options, or **claims** in the JWT lingo. You can use the
|
||||
```
|
||||
|
||||
- **`value_exists`** - This is a claim that can be used to validate the token against the data stored in a collection. Structure of this claim is as follows:
|
||||
|
||||
|
||||
```json
|
||||
{
|
||||
"value_exists": {
|
||||
@@ -279,7 +279,7 @@ These are the available options, or **claims** in the JWT lingo. You can use the
|
||||
```
|
||||
|
||||
If this claim is present, Qdrant will check if there is a point in the collection with the specified key-values. If it does, the token is valid.
|
||||
|
||||
|
||||
This claim is especially useful if you want to have an ability to revoke tokens without changing the `api_key`.
|
||||
Consider a case where you have a collection of users, and you want to revoke access to a specific user.
|
||||
|
||||
@@ -336,10 +336,10 @@ These are the available options, or **claims** in the JWT lingo. You can use the
|
||||
}
|
||||
```
|
||||
|
||||
This `payload` claim will be used to implicitly filter the points in the collection. It will be equivalent to appending this filter to each request:
|
||||
This `payload` claim will be used to implicitly filter the points in the collection. It will be equivalent to appending this filter to each request:
|
||||
|
||||
```json
|
||||
{ "filter": { "must": [{ "key": "user_id", "match": { "value": "user_123456" } }] } }
|
||||
```json
|
||||
{ "filter": { "must": [{ "key": "user_id", "match": { "value": "user_123456" } }] } }
|
||||
```
|
||||
|
||||
### Table of access
|
||||
@@ -352,7 +352,7 @@ This is also applicable to using api keys instead of tokens. In that case, `api_
|
||||
|
||||
| Action | manage | read-only | collection read-write | collection read-only | collection with payload claim (r / rw) |
|
||||
|--------|--------|-----------|----------------------|-----------------------|------------------------------------|
|
||||
| list collections | ✅ | ✅ | 🟡 | 🟡 | 🟡 |
|
||||
| list collections | ✅ | ✅ | 🟡 | 🟡 | 🟡 |
|
||||
| get collection info | ✅ | ✅ | ✅ | ✅ | ❌ |
|
||||
| create collection | ✅ | ❌ | ❌ | ❌ | ❌ |
|
||||
| delete collection | ✅ | ❌ | ❌ | ❌ | ❌ |
|
||||
@@ -523,4 +523,9 @@ We recommend reducing the amount of permissions granted to Qdrant containers so
|
||||
- You can set [`read_only: true`](https://docs.docker.com/compose/compose-file/05-services/#read_only) when using Docker Compose.
|
||||
- You can set [`readOnlyRootFilesystem: true`](https://kubernetes.io/docs/tasks/configure-pod-container/security-context) when running in Kubernetes (our [Helm chart](https://github.com/qdrant/qdrant-helm) does this by default).
|
||||
|
||||
There are other techniques for reducing the permissions such as dropping [Linux capabilities](https://www.man7.org/linux/man-pages/man7/capabilities.7.html) depending on your deployment method, but running as a non-root user with a read-only root file system are the two most important.
|
||||
* Block Qdrant's external network access. This can help mitigate [server side request forgery attacks](https://owasp.org/www-community/attacks/Server_Side_Request_Forgery), like via the [snapshot recovery API](https://api.qdrant.tech/api-reference/snapshots/recover-from-snapshot). Single-node Qdrant clusters do not require any outbound network access. Multi-node Qdrant clusters only need the ability to connect to other Qdrant nodes via TCP ports 6333, 6334, and 6335.
|
||||
- You can use [`docker network create --internal <name>`](https://docs.docker.com/reference/cli/docker/network/create/#internal) and use that network when running [`docker run --network <name>`](https://docs.docker.com/reference/cli/docker/container/run/#network).
|
||||
- You can create an [internal network](https://docs.docker.com/compose/compose-file/06-networks/#internal) when using Docker Compose.
|
||||
- You can create a [NetworkPolicy](https://kubernetes.io/docs/concepts/services-networking/network-policies/) when using Kubernetes. Note that multi-node Qdrant clusters [will also need access to cluster DNS in Kubernetes](https://github.com/ahmetb/kubernetes-network-policy-recipes/blob/master/11-deny-egress-traffic-from-an-application.md#allowing-dns-traffic).
|
||||
|
||||
There are other techniques for reducing the permissions such as dropping [Linux capabilities](https://www.man7.org/linux/man-pages/man7/capabilities.7.html) depending on your deployment method, but the methods mentioned above are the most important.
|
||||
|
||||
@@ -5,7 +5,7 @@ weight: 1
|
||||
|
||||
# Creating a Hybrid Cloud Environment
|
||||
|
||||
The following instruction set will show you how to properly setup a **Qdrant cluster** in your **Hybrid Cloud Environment**.
|
||||
The following instruction set will show you how to properly set up a **Qdrant cluster** in your **Hybrid Cloud Environment**.
|
||||
|
||||
To learn how Hybrid Cloud works, [read the overview document](/documentation/hybrid-cloud/).
|
||||
|
||||
@@ -22,6 +22,15 @@ To learn how Hybrid Cloud works, [read the overview document](/documentation/hyb
|
||||
|
||||
> **Note:** You can also mirror these images and charts into your own registry and pull them from there.
|
||||
|
||||
### CLI tools
|
||||
|
||||
During the onboarding, you will need to deploy the Qdrant Kubernetes Operator and Agent using Helm. Make sure you have the following tools installed:
|
||||
|
||||
* [kubectl](https://kubernetes.io/docs/tasks/tools/install-kubectl/)
|
||||
* [helm](https://helm.sh/docs/intro/install/)
|
||||
|
||||
You will need to have access to the Kubernetes cluster with `kubectl` and `helm` configured to connect to it. Please refer the documentation of your Kubernetes distribution for more information.
|
||||
|
||||
### Required artifacts
|
||||
|
||||
Container images:
|
||||
@@ -29,7 +38,7 @@ Container images:
|
||||
- `docker.io/qdrant/qdrant`
|
||||
- `registry.cloud.qdrant.io/qdrant/qdrant-cloud-agent`
|
||||
- `registry.cloud.qdrant.io/qdrant/qdrant-operator`
|
||||
- `registry.cloud.qdrant.io/qdrant/qdrant-cloud-cluster-manager`
|
||||
- `registry.cloud.qdrant.io/qdrant/cluster-manager`
|
||||
- `registry.cloud.qdrant.io/qdrant/prometheus`
|
||||
- `registry.cloud.qdrant.io/qdrant/prometheus-config-reloader`
|
||||
- `registry.cloud.qdrant.io/qdrant/kube-state-metrics`
|
||||
@@ -38,6 +47,7 @@ Open Containers Initiative (OCI) Helm charts:
|
||||
|
||||
- `registry.cloud.qdrant.io/qdrant-charts/qdrant-cloud-agent`
|
||||
- `registry.cloud.qdrant.io/qdrant-charts/qdrant-operator`
|
||||
- `registry.cloud.qdrant.io/qdrant-charts/qdrant-cluster-manager`
|
||||
- `registry.cloud.qdrant.io/qdrant-charts/prometheus`
|
||||
|
||||
## Installation
|
||||
@@ -53,6 +63,8 @@ Open Containers Initiative (OCI) Helm charts:
|
||||
- **Name:** A name for the Hybrid Cloud Environment
|
||||
- **Kubernetes Namespace:** The Kubernetes namespace for the operator and agent. Once you select a namespace, you can't change it.
|
||||
|
||||
You can also configure the StorageClass and VolumeSnapshotClass to use for the Qdrant databases, if you want to deviate from the default settings of your cluster.
|
||||
|
||||
4. You can then enter the YAML configuration for your Kubernetes operator. Qdrant supports a specific list of configuration options, as described in the [Qdrant Operator configuration](/documentation/hybrid-cloud/operator-configuration/) section.
|
||||
|
||||
5. (Optional) If you have special requirements for any of the following, activate the **Show advanced configuration** option:
|
||||
@@ -84,6 +96,15 @@ You need this command only for the initial installation. After that, you can upd
|
||||
|
||||
Once you have created a Hybrid Cloud Environment, you can create a Qdrant cluster in that enviroment. Use the same process to [Create a cluster](/documentation/cloud/create-cluster/). Make sure to select your Hybrid Cloud Environment as the target.
|
||||
|
||||
Note that in the "Kubernetes Configuration" section you can configure:
|
||||
|
||||
* Node selectors for the Qdrant database pods
|
||||
* Toleration for the Qdrant database pods
|
||||
* Additional labels for the Qdrant database pods
|
||||
* A service type and annotations for the Qdrant database service
|
||||
|
||||
These settings can also be changed after the cluster is created on the cluster detail page.
|
||||
|
||||
### Authentication at your Qdrant clusters
|
||||
|
||||
In Hybrid Cloud the authentication information is provided with Kubernetes secrets.
|
||||
@@ -124,7 +145,18 @@ kubectl -n qdrant-namespace port-forward service/qdrant-9a9f48c7-bb90-4fb2-816f-
|
||||
|
||||
You can also expose the database outside the Kubernetes cluster with a `LoadBalancer` (if supported in your Kubernetes environment) or `NodePort` service or an ingress.
|
||||
|
||||
A simple Loadbalancer service could look like this:
|
||||
The service type and necessary annotations can be configured in the "Kubernetes Configuration" section during cluster creation, or on the cluster detail page.
|
||||
|
||||
Especially if you create a LoadBalancer Service, you may need to provider annotations for the loadbalancer configration. Please refer to the documention of your cloud provider for more details.
|
||||
|
||||
Examples:
|
||||
|
||||
* [AWS EKS LoadBalancer annotations](https://kubernetes-sigs.github.io/aws-load-balancer-controller/latest/guide/ingress/annotations/)
|
||||
* [Azure AKS Public LoadBalancer annotations](https://learn.microsoft.com/en-us/azure/aks/load-balancer-standard)
|
||||
* [Azure AKS Internal LoadBalancer annotations](https://learn.microsoft.com/en-us/azure/aks/internal-lb)
|
||||
* [GCP GKE LoadBalancer annotations](https://cloud.google.com/kubernetes-engine/docs/concepts/service-load-balancer-parameters)
|
||||
|
||||
You could also create a Loadbalancer service manually like this:
|
||||
|
||||
```yaml
|
||||
apiVersion: v1
|
||||
|
||||
@@ -7,8 +7,6 @@ aliases:
|
||||
|
||||
# Introduction
|
||||
|
||||

|
||||
|
||||
Vector databases are a relatively new way for interacting with abstract data representations
|
||||
derived from opaque machine learning models such as deep learning architectures. These
|
||||
representations are often called vectors or embeddings and they are a compressed version of
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
---
|
||||
stats:
|
||||
githubStars: 18.8k
|
||||
discordMembers: 6.0k
|
||||
githubStars: 18.9k
|
||||
discordMembers: 6.1k
|
||||
twitterFollowers: 7.5k
|
||||
---
|
||||
Reference in New Issue
Block a user